235 stories
·
1 follower

Sie wollen eine Pause. Es wird keine geben

1 Share

OpenAI will 2026 nicht mehr an die Börse. Die Begründung, die Sam Altman offiziell gibt ist AI Safety. Zugleich erklärt er sich bereit, die Entwicklung leistungsfähiger Modelle gemeinsam mit anderen Labs zu verlangsamen. Anthropic fordert ebenfalls eine koordinierte Pause.

Ich glaube denen den Wunsch nach der Pause, aber ich glaube die Geschichte dahinter nicht.

Die AI-Firmen entdecken die Notwendigkeit einer Pause genau in dem Moment, in dem ihnen die Finanzierung davonläuft, ein Börsengang ihre kaputten Economics offenlegen würde und Open-Weights-Modelle anfangen, auf Rechnern unter einem Schreibtisch nützlich zu werden.

Das ist kein Zufall. Die Pause soll nicht den amoklaufenden Maschinengott aufhalten, sondern einen Investitionszyklus verlängern, der seine Kosten absehbar nicht mehr einspielen kann.

Die Kreditmaschine

AI sieht von außen wie ein Softwaregeschäft aus, aber in Wahrheit ist Frontier AI eine kapitalintensive Schwerindustrie.

Man braucht Grundstücke, Hallen, Umspannwerke, Stromverträge, Kühlung, Netzwerk, RAM, NVMe und sehr große Mengen Beschleuniger. Die Softwaremargen kommen erst danach, falls überhaupt.

Die Anbieter haben diese Infrastruktur nicht aus laufenden Einnahmen bezahlt. Stattdessen haben sie eine Kreditmaschine gebaut:

  • OpenAI, Anthropic, xAI und andere versprechen langfristigen Compute-Bedarf.
  • Oracle, CoreWeave und die Hyperscaler bestellen Hardware und Rechenzentren.
  • Banken, Anleihemärkte, Private Credit und Zweckgesellschaften finanzieren den Bau.
  • Hersteller und Rechenzentrumsentwickler bekommen Abnahmegarantien.
  • Die Verträge werden als Begründung für die nächste Finanzierungsrunde verwendet.

Dabei entstehen überall Umsätze, Forderungen, Backlogs und Bewertungen. Cash entsteht sehr viel später, und der einzige Weg, auf dem Cash entstehen kann, ist wenn Unternehmen AIaaS kaufen und Token abnehmen. Und es sieht zunehmen so aus, als müssten sie das nicht tun.

Die Finanzierungen sind zum Teil überzeichnet. Das klingt gesund, bedeutet aber nur, daß mehr Investoren eine hoch verzinste und gut besicherte Forderung kaufen wollen, als die Emission groß ist. CoreWeave konnte im Mai 2026 eine überzeichnete Finanzierung während der Syndizierung sogar um 50 Basispunkte billiger bekommen.

Der Markt ist nicht leer. Das billige, unbesicherte und bedingungsarme Kapital ist leer.

Deswegen wandert die Finanzierung in besicherte Kredite, GPU-backed Loans, Project Finance, Sale-and-Leaseback, Private Credit, ausländische Anleihemärkte und Staatsfonds. Die OECD erwartet , daß Private Credit in vier Jahren ungefähr 800 Milliarden USD zur AI-Expansion beitragen soll. Sie schreibt im selben Bericht, daß selbst das für den geplanten Ausbau nicht reicht.

CoreWeave

CoreWeave ist die Kreditmaschine ohne Verkleidung.

Zum 30. Juni 2026 hatte die Firma 35,6 Milliarden USD Schulden . Davon werden 4,4 Milliarden noch 2026 und 6,2 Milliarden 2027 fällig. Einige Kredite kosten effektiv zwischen 9 und 15 Prozent.

Im ersten Halbjahr 2026 gingen 5,2 Milliarden USD in Tilgung und 982 Millionen in Zinsen. Der Nettozinsaufwand in der Ergebnisrechnung betrug 1,18 Milliarden USD. CoreWeave machte im selben Zeitraum 4,7 Milliarden USD Umsatz und 1,37 Milliarden USD Verlust.

Das Unternehmen muß weiter investieren, um die bereits abgeschlossenen Kundenverträge bedienen zu können. Es muß zugleich alte Finanzierungen tilgen, während es neue aufnimmt. Seine eigene Risikobeschreibung sagt ausdrücklich, daß ungünstigere Kreditbedingungen die Erfüllung von Kundenverträgen verhindern können.

Das ist kein Softwareunternehmen mit etwas Fremdkapital. Das ist eine gehebelte Wette auf drei Annahmen:

  • Die Großkunden bleiben zahlungsfähig.
  • Sie nehmen die bestellte Kapazität tatsächlich ab.
  • Die Hardware bleibt lange genug wirtschaftlich ausgelastet.

Wenn eine dieser Annahmen fällt, hat CoreWeave keine zweite Ertragsmaschine, die den Fehler bezahlt.

Oracle

Oracle hat immerhin ein altes und profitables Softwaregeschäft. Die Firma setzt es aber vollständig als Sicherheit für die AI-Wette ein.

Im Geschäftsjahr 2026 nahm Oracle 43 Milliarden USD neue Schulden und fünf Milliarden USD Eigenkapital auf. Zwischen Juni und August 2026 verkaufte die Firma weitere Aktien für 20 Milliarden USD .

Am 31. August 2026 standen 125 Milliarden USD kurz- und langfristige Kredite in der Bilanz. Dazu kommen 31 Milliarden USD Operating-Lease-Verbindlichkeiten und 288 Milliarden USD bereits unterschriebene zusätzliche Lease Commitments, fast vollständig für Rechenzentren. Die meisten davon beginnen bis 2029 und laufen danach 15 bis 19 Jahre.

Diese 288 Milliarden stehen noch nicht als Verbindlichkeit in der Bilanz, weil die betreffenden Leases noch nicht begonnen haben. Unterschrieben sind sie trotzdem.

Auf der anderen Seite stehen 664 Milliarden USD Remaining Performance Obligations. Das sind vertraglich erwartete zukünftige Umsätze. Es ist kein Geld auf dem Konto. Es ist nicht einmal notwendigerweise profitabler Umsatz.

Oracle hat also langfristige Verpflichtungen aufgenommen, um zukünftigen Umsatz mit wenigen sehr großen AI-Kunden zu bedienen. Das kann funktionieren. Es funktioniert genau so lange, wie die Kunden zahlen und der Preis für Compute nicht schneller fällt als die Kosten der Verpflichtungen.

Oracle ist damit der systemisch interessantere Fall, denn CoreWeave kann alleine platzen, aber Oracle kann Kreditmärkte, Leasinggesellschaften, Zulieferer und Aktionäre mitnehmen.

Die Hyperscaler folgen

Meta, Microsoft und Alphabet sind nicht CoreWeave in groß – noch nicht.

Sie besitzen profitable Kerngeschäfte, aus denen sie den Ausbau bezahlen können. Aber auch ihre Bilanzen werden durch AI sichtbar umgebaut.

Meta hatte Ende Juni 83,7 Milliarden USD langfristige Schulden und 349 Milliarden USD nicht kündbare vertragliche Verpflichtungen . Die meisten Verpflichtungen betreffen fremde Cloud-Kapazität und andere technische Infrastruktur.

Alphabet hatte 98,2 Milliarden USD langfristige Schulden und beschaffte im zweiten Quartal weitere 20,5 Milliarden am Anleihemarkt. Das Geld ist ausdrücklich auch für AI-Infrastruktur bestimmt.

Microsoft plant für das Kalenderjahr 2026 inzwischen ungefähr 175 Milliarden USD Capex . Die Zahl ist bereits geschönt, weil Microsoft zukünftige Rechenzentrumsverträge vermehrt als Operating Leases statt als Finance Leases strukturieren will. Operating Leases erscheinen nicht im ausgewiesenen Capex. Bezahlt werden müssen sie trotzdem.

Diese Firmen sind noch nicht in einer Liquiditätskrise. Sie sind in einer Kapitalallokationskrise: Ihre alten Geschäfte erwirtschaften Geld, das in immer schneller alternde AI-Infrastruktur umgeleitet wird. Mit jedem Jahr wird es schwieriger, einen solchen Ausbau aus dem Cashflow zu bezahlen. Also gehen auch die größten Firmen der Welt an die Kreditmärkte.

Irgendwann konkurrieren Oracle, CoreWeave, Meta, Microsoft, Alphabet, Amazon, OpenAI, Anthropic und xAI nicht mehr nur um GPUs und Strom. Sie konkurrieren um denselben Kredit.

Was eine Börse sichtbar macht

OpenAI und Anthropic wollten an die Börse. OpenAI hat dafür im Juni 2026 vertraulich Unterlagen eingereicht. Nun wird der Börsengang auf mindestens 2027 verschoben . Die offizielle Begründung lautet AI Safety.

Ein Börsengang bringt Geld. Er bringt aber auch geprüfte Abschlüsse, Material Contracts, Related-Party Transactions, Kundenkonzentration, Leases, Kaufverpflichtungen, Risikofaktoren und quartalsweise Berichte.

Er liefert nicht automatisch eine hübsche Tabelle mit Inference Cost pro Token. Aber er liefert genug Daten, um die tatsächlichen Kosten zu rekonstruieren:

  • Umsatzqualität statt annualisierter Run Rate,
  • Gross Margin nach Inference Cost,
  • Abschreibungen auf Beschleuniger,
  • Strom-, Netzwerk- und Speicherkosten,
  • langfristige Compute-Verträge,
  • Mindestabnahmen,
  • Kundenkonzentration,
  • Cash Burn,
  • Related-Party- und Ringfinanzierungen.

Dann werden OpenAI, Anthropic, CoreWeave, Oracle und die Hyperscaler vergleichbar. Sie wollen nicht vergleichbar sein.

xAI zeigt inzwischen unfreiwillig, warum. Vor der Verschmelzung mit SpaceX war die Firma eine schwarze Kiste. Nach dem SpaceX-Börsengang muß sie als Teil des AI-Segments berichtet werden.

Das AI-Segment von SpaceX verlor im zweiten Quartal 2026 operativ 1,26 Milliarden USD, im ersten Halbjahr 3,73 Milliarden. Frühere xAI-Kredite und Anleihen kosteten 12,5 Prozent. Ihre vorzeitige Rückzahlung erzeugte ungefähr 739 Millionen USD Vorfälligkeitskosten. Dazu kommen mehr als 13 Milliarden USD Finanzierungsschulden aus Transaktionen, die als Sale-and-Leaseback geplant waren, aber bilanziell nicht als Verkauf anerkannt wurden.

Vor dem IPO waren das Vermutungen, aber nach dem IPO ist es eine Tabelle in der Bilanz.

OpenAI will diese Tabelle derzeit nicht veröffentlichen.

Die Laufzeiten passen nicht zusammen

Rechenzentren werden über 15 bis 20 Jahre finanziert. Stromanschlüsse, Hallen und Leitungen können so lange halten. Beschleuniger tun es nicht.

Microsoft sagt selbst, daß ungefähr zwei Drittel seines aktuellen Capex in kurzlebige Assets gehen, hauptsächlich GPUs und CPUs. Die Hardware altert in wenigen Jahren. Die Modelle und Inferenzverfahren altern in Monaten.

Auf der Einnahmeseite sind die Laufzeiten teilweise viel kürzer. SpaceX schreibt zum Beispiel, daß seine AI-Cloud-Verträge nach der Anlaufphase mit 90 Tagen Frist gekündigt werden können. In demselben Risikokapitel steht, daß effizientere Modelle und alternative Architekturen die Nachfrage nach Infrastruktur reduzieren können.

Das ist der Kern des Problems:

Die Kredite laufen langsamer ab als die damit beschafften Werte, die den technischen Burggraben bauen sollen, um den Vorsprung zu sichern.

Dazu kommt: Ein Rechenzentrum kann ausgelastet sein und trotzdem eine schlechte Investition werden. Wenn der Marktpreis für dieselbe Aufgabe schneller fällt als Strom, Zins und Abschreibung, erzeugt mehr Nutzung keine gute Marge.

Wir haben dadurch die Situation, daß zugleich die AI-Nutzung explodieren kann, aber AIaaS als Modell nicht ertragreich realisiert werden kann, weil es die erwarteten fantastischen Margen nicht liefern kann. Es generiert höchstens gewöhnliches Hosting mit gewöhnlichen Cloud-Margen.

Moore’s Law für Inferenz

Es gibt kein Moore’s Law für Inferenz . Es gibt keine Industrie-Roadmap, die alle zwei Jahre verläßlich doppelt so viele brauchbare Transistoren zum selben Preis garantiert.

Es gibt aber gerade eine Entwicklung mit derselben wirtschaftlichen Wirkung, die sich vielleicht bis zu einem gewissen Punkt stabilsieren läßt.

Denn alle paar Monate werden Modelle besser, während der Aufwand pro Token sinkt. Der genaue Faktor ist nicht wichtig. Wichtig ist, daß die Faktoren multipliziert werden.

Die Fortschritte kommen aus vielen Richtungen gleichzeitig:

  • kleinere und besser trainierte Dense Models,
  • Quantisierung,
  • Mixture of Experts mit wenigen aktiven Parametern pro Token,
  • kleinere KV-Caches,
  • Gated, Linear und Sparse Attention,
  • Multi-Token Prediction,
  • schnellere Speculative Decoding-Verfahren,
  • mehr Speicherbandbreite durch integriertes LPDDR,
  • getrennte heiße und kalte Modellteile,
  • Streaming selten verwendeter Daten aus RAM und NVMe.

Der letzte Punkt ist neu und wichtig.

Qwen3.8-Flash-Next hat ein Hauptmodell mit 125 Milliarden Parametern, aktiviert aber nur sechs Milliarden pro Token. Dazu kommen weitere 51 Milliarden Parameter als N-Gram-Embedding-Tabelle. Diese Tabelle funktioniert eher wie ein riesiges Dictionary als wie der heiße Kern des Modells. Die Adressen der benötigten Einträge stehen früh fest. Man kann sie aus Host Memory vorladen, während die GPU bereits rechnet. Das bedeutet, während das Modell 90 GB auf der Platte belegt, kommt es mit einem In-Memory Footprint von nur 64 GB, und generiert mit 6 Milliarden aktiven Parametern einen Working Set von einigen GB.

DeepSeek-V4.1-Flash verwendet denselben Grundgedanken mit Engram Conditional Memory: 552 Milliarden Parameter im Backbone, weitere 196 Milliarden in einer dünn angesprochenen Lookup-Struktur und nur acht beziehungsweise 16 Milliarden aktive Parameter für Prefill und Decode.

Solche Tabellen müssen nicht dauerhaft in HBM liegen. Die heißen Teile gehören auf den Beschleuniger, warme Daten in billigeres LPDDR oder normales RAM und kalte, vorhersagbar gelesene Tabellen auf NVMe. Das Modell wird zu einer Speicherhierarchie.

Damit wird aus einem teuren HBM-Problem teilweise ein billiges Lookup-Problem. Das wird ein Standardwerkzeug für LLM-Architekturen werden.

Und die Geschwindigkeit ist mit ( Speicherbandbreite / Anzahl der aktiven Parameter skaliert mit der Quantisierung ) abschätzbar. Ein “A6B” Modell als Q4 hat 3 GB aktiv. Ein M5max mit 634 GB/s kann also circa 210 Token/s generieren, aus einem Modell, das 90 GB auf der Platte belegt.

Low Terra auf einem Mac

Die wirtschaftliche Frist ist keine theoretische Zukunft.

Qwen3.8-27B läuft quantisiert auf einem Mac mit 32 GB Unified Memory gut. Das Modell hat brauchbares Niveau für Software-Entwicklung, es ist vergleichbar einem etwas schlechteren GPT-5.6 Terra (Medium) in dieser Domain. Es ist langsam im Vergleich zu einem Modell aus dem Rechenzentrum mit einem Cluster von H200, aber schnell genug zum Arbeiten.

Ein Terra-class Modell ist für den Specialization Workflow bereits ausreichend. Der normale Workflow verwendet:

  1. Sol mit ‘medium’ für die Entwicklung der User Stories.
  2. Terra mit ‘medium’für die Ableitung der Implementation Tickets.
  3. Luna mit ‘xhigh’ für die Codegenerierung.

Die erste Phase braucht das stärkere Modell (und menschlichen Review), weil dort aus einer unscharfen Idee belastbare Anforderungen entstehen. Fehler an dieser Stelle werden in allen späteren Schritten multipliziert.

Die zweite und dritte Phase sind bereits spezialisiert. Die abgenommenen User Stories beschränken die Tickets. Die abgenommenen Tickets beschränken den Code. Tests, Linter, Type Checker und Reviews liefern mechanische Grenzen.

Für diese beiden Phasen reicht niedriges Terra-Niveau absolut aus. Qwen3.8-27B kann sie lokal erledigen.

Das bedeutet: Zwei der drei Produktionsphasen eines realen Software-Workflows brauchen schon heute keine zentralisierte Inferenz mehr. Gerade dort entsteht aber die Masse der Requests und Token.

Die großen Modelle werden für Architektur, schwierige Reviews und die Verdichtung der Anforderungen gebraucht. Die alltägliche Ticketarbeit und Codeproduktion kann lokal laufen.

Rechner mit 128 GB gemeinsam nutzbarem Speicher sind ebenfalls keine exotischen Server mehr. AMD Ryzen AI Max stellt bis zu 96 GB von 128 GB RAM für die GPU bereit. Nvidias DGX Spark hat 128 GB kohärenten LPDDR5x-Speicher und vier TB NVMe auf dem Schreibtisch. Apple verkauft dieselbe Grundidee als großen Laptop oder Mac Studio.

Auf dieser Klasse läuft heute hohes Terra-Niveau und absehbar niedriges Sol-Niveau, langsamer als im Rechenzentrum, aber lokal, privat und ohne Preis pro Token.

Bessere Modelle erhöhen den Druck

Man könnte annehmen, daß ein neues stärkeres Frontier-Modell den zentralen Anbietern wieder Abstand verschafft. Vielleicht ist das auch so, für manche Anwendungen. Für “SWE” (Software Engineering) ist was wir haben aber in der Regel ausreichend.

Und der Druck wird größer:

Wenn wir alle drei Monate die Leistung verdoppeln und zugleich den Inferenzaufwand halbieren, ist das wirtschaftlich eine Vervierfachung. Faktor 100 sind nicht hundert Generationen. Es sind mehr als drei und weniger als vier solche Schritte:

4³ = 64
4⁴ = 256

Ob jeder einzelne Schritt exakt nach drei Monaten kommt ist nicht wichtig. Die heutigen Rechenzentren sind auf Laufzeiten von bis zu 19 Jahren finanziert. Selbst eine deutlich langsamere Verbesserung gewinnt dieses Rennen.

Es wird keine Pause geben

Eine koordinierte Pause wäre für die westlichen Anbieter ideal.

OpenAI, Anthropic, Google, Meta und xAI könnten den Frontier-Wettlauf verlangsamen. Sie würden weniger neues Capex brauchen, die Lebensdauer der vorhandenen Modelle verlängern und die Preise länger oben halten.

Das ist ein klassisches Abrüstungsproblem. Jeder einzelne Anbieter muß weiter investieren, weil ein anderer sonst die Capability Leadership übernimmt. Gemeinsam wären sie finanziell besser gestellt, wenn alle weniger investierten.

Also nennt man die gewünschte Koordination AI Safety.

Das Problem ist: China nimmt an diesem Abrüstungsabkommen nicht teil. DeepSeek, Qwen, GLM, Kimi, MiMo und ihre Nachfolger werden weiterentwickelt. Open Weights werden veröffentlicht, kopiert, quantisiert, destilliert und auf neue Hardware portiert.

Ein veröffentlichtes Modell kann man nicht zurückrufen. Es liegt auf privaten Rechnern, in Firmenarchiven und auf Rechnern außerhalb der USA. Selbst wenn morgen alle westlichen Labs stillstehen, arbeitet die bereits veröffentlichte Technik weiter.

Trump hat eine Pause zunächst mit dem korrekten Argument abgelehnt, daß die USA damit den Vorsprung an China abgeben würden. Die Pause wird die amerikanische Dominanz schwächen: mehr nicht-amerikanische und nicht-kontrollierte AI.

Regulatory Capture

Wenn die technische Pause nicht funktioniert, bleibt eine regulatorische.

Das Ziel ist nicht unbedingt ein ausdrückliches Besitzverbot für leistungsfähige Rechner. Das wäre auffällig, schwer durchsetzbar und schnell technisch veraltet. Es reicht, den gewerblichen Einsatz lokaler und offener Modelle unpraktikabel zu machen.

Die Werkzeuge dafür existieren:

  • Zertifizierungs- und Auditpflichten für Modelle und Betreiber,
  • Registrierung großer Modelle und Compute-Installationen,
  • verpflichtendes Logging und zentralisierte Überwachung,
  • persönliche Haftung von Geschäftsführern,
  • Versicherungspflichten,
  • Cloud-KYC und Herkunftsnachweise für Modelle,
  • Procurement-Regeln für Staat und regulierte Branchen,
  • Ausschluß nicht zertifizierter Open Weights,
  • Exportkontrollen auf Beschleuniger, Speicher und Model Weights,
  • Einschränkungen gegen chinesische Modelle aus Gründen der Nationalen Sicherheit.

Privat darf man das Modell dann vielleicht noch besitzen. Eine Bank, Versicherung, Behörde, Arztpraxis oder größere Firma darf es nicht mehr einsetzen. Für sie bleibt nur ein zertifizierter Managed Service.

Damit wird aus AI Safety ein Schutzwall für AIaaS.

Das Cornern von GPU-, RAM- und NVMe-Märkten ergänzt diesen Schutzwall. Wer Rechenzentren für Jahre im voraus mit Beschleunigern, HBM, DRAM und Flash versorgt, verteuert gleichzeitig die lokale Konkurrenz. Der Effekt ist bereits sichtbar: leistungsfähige GPUs, große RAM-Ausstattungen und schnelle NVMe sind knapp und teuer.

Der Gegeneffekt ist auch bereits sichtbar: CXML und andere chinesische Anbieter machen sich bereit, die so entstande Nachfrage zu befriedigen.

Am Ende hält all das die Entwicklung nicht auf. Es verschiebt sie zu Architekturen, die weniger von jedem knappen Gut brauchen. MoE, Quantisierung, kleine KV-Caches, LPDDR und NVMe-Streaming sind genau die Antwort auf einen gecornerten Hardwaremarkt. Das bedeutet: Wir bekommen auf jeden Fall mehr und leistungsfähigere Modelle, die optimiert darauf sind, auf lokaler Hardware befriedigende Leistung zu bringen.

Wenn es aber um regulatory capture geht, dann kann die EU dabei als williger Marktvernichter dienen. Je komplexer Registrierung, Haftung und Zertifizierung werden, desto weniger europäische Firmen können eigene Modelle betreiben. US-Hyperscaler können die Compliance-Kosten auf Millionen Kunden verteilen. Ein Mittelständler mit einem offenen Modell kann das nicht.

Die Regulierung schützt dann nicht Europa vor amerikanischer AI. Sie schützt amerikanische AI vor europäischer Konkurrenz.

Der Exit

Für die AI-Investitionen gibt es nur wenige mögliche Auswege aus dem aktuellen Szenario:

Ein reguliertes Oligopol kann die Preise hochhalten und die vorhandenen Verpflichtungen auf die Kunden umlegen.

Open Weights können AI kommoditisieren. Dann überleben Rechenzentren und Hosting, aber die außergewöhnlichen AIaaS-Margen verschwinden.

Ein großer Kunde kann ausfallen oder Verträge reduzieren. Dann beginnt der Kreditunfall bei CoreWeave oder einem Oracle-Projekt und die Ansteckung läuft durch Zweckgesellschaften, Leasingfirmen, Banken und Private Credit.

Die Hyperscaler können ihre Fehlallokationen abschreiben. Ihre Werbe-, Office- und Cloud-Geschäfte werden das überleben. Aktionäre und Mitarbeiter bezahlen die Rechnung.

Oder der Staat sichert die Investitionen indirekt: mit Kreditgarantien, Stromverträgen, beschleunigten Genehmigungen, Rüstungs- und Behördenaufträgen und einer Regulierung, die Nachfrage nach den zugelassenen Anbietern erzwingt.

Eine formelle Verstaatlichung ist dafür nicht nötig. Gewinne bleiben privat. Das Risiko kann man auch so sozialisieren.

Die Modelle werden billiger, die Schulden nicht

Der Börsengang würde zeigen, wie schlecht die Unit Economics der Frontier-Anbieter tatsächlich sind. Deshalb wird er verschoben.

Die Pause würde den Capex-Wettlauf bremsen, die vorhandenen Modelle länger verwertbar machen und Zeit für regulatorische Schutzwälle kaufen. Deshalb wird sie verlangt.

Aber die Pause wird nicht stattfinden.

China entwickelt weiter. Open Weights sind bereits publiziert. Architekturen werden effizienter. 32-GB-Rechner erledigen heute Arbeiten, für die vor kurzem noch ein proprietärer Cloud-Service notwendig war. 128-GB-Rechner bringen die nächste Modellklasse auf den Schreibtisch.

Die Branche hat Rechenzentren für bis zu 19 Jahre bestellt, aber ihr Vorsprung wird in Quartalen gemessen.

Sie wollen eine Pause. Es wird keine geben.

Read the whole story
jhunorss
11 hours ago
reply
Share this story
Delete

Your Loom App Quietly Became a Thread Pool Again: A Field Guide to Virtual Thread Pinning

1 Share

The incident that taught me to respect pinning looked like nothing. A service freshly migrated to virtual threads, a load test that plateaued at about 420 requests per second no matter how much traffic we threw at it, CPU sitting at 9%, zero errors, zero warnings, nothing in the logs. The machine had 8 cores, and the one downstream HTTP call in the hot path took about 19 ms. Do the arithmetic: 8 × (1000 / 19) ≈ 421.

The service that was supposed to scale to millions of virtual threads was serving exactly one request per CPU core. Loom had quietly handed us back a bounded thread pool, and the code looked perfectly innocent. That failure mode has a name — pinning — and this is the field guide I wish I'd had that night: what it is, the two (and only two) things that cause it, what JDK 24 changed, and how to catch it before your throughput graph does.

What pinning actually is

A virtual thread doesn't own an OS thread. It runs on a small pool of platform threads called carrier threads — concretely, the workers of a dedicated ForkJoinPool living in a thread group named CarrierThreads, with default parallelism equal to Runtime.availableProcessors(). When a virtual thread blocks — on I/O, a lock, a queue — it normally unmounts: it saves its stack, steps off the carrier, and frees that carrier to run another virtual thread. That unmount is the entire trick that lets a handful of OS threads serve millions of virtual ones.

Pinning is when the unmount can't happen. The virtual thread blocks but stays mounted, and its carrier sits there doing nothing useful for the whole duration. One pinned carrier is a rounding error. But the default carrier pool is only as big as your core count, so if a hot path pins routinely, you pin every carrier at once — and then no virtual thread anywhere makes progress. That's not a slowdown; it's scheduler starvation, and from the outside it looks a lot like a deadlock. You can raise the ceiling with -Djdk.virtualThreadScheduler.parallelism=N, but that only delays the moment of exhaustion. It doesn't fix anything.

The two causes — and it really is just two

There are exactly two situations where the JVM cannot unmount a blocked virtual thread:

1. Blocking inside synchronized (JDK 21 through 23). Up to and including JDK 23, an object monitor is tied to the carrier thread that entered it. If a virtual thread blocks — or calls Object.wait() — while holding a monitor, the JVM can't move it off the carrier without breaking monitor ownership, so it pins. This is by far the most common cause in real code, because a blocking call buried inside a synchronized method is trivial to write and invisible at the call site. And the monitor doesn't have to be yours: synchronized inside a library, or inside the JDK itself, pins exactly the same way. ConcurrentHashMap.computeIfAbsent runs your mapping function under an internal bin lock — put a blocking call inside it and you've pinned a carrier without a single synchronized keyword in your own code.

2. Native frames. When a virtual thread has a native method (JNI) or a foreign downcall (the Foreign Function & Memory API) on its stack and it blocks, the JVM can't capture and restore the native frame, so it pins. This one has no synchronized to blame — and it is not fixed by JDK 24. It also hides in a place nobody expects: class initialization runs through native frames, so a blocking call inside a static initializer pins even on the newest JDKs.

Just as important is what's not on the list: ordinary blocking I/O through the JDK (Socket, InputStream, Files), BlockingQueue, ReentrantLock, CompletableFuture, Thread.sleep() — all of it was re-plumbed for Loom and unmounts cleanly. Pinning is a short, specific list, which is exactly why it's detectable.

The canonical bug

Nearly every real pin I've read in a dump is some flavor of a cache or rate limiter guarding a slow call with synchronized:

public class PriceService {
    private final Map<String, BigDecimal> cache = new HashMap<>();

    // Looks harmless. On JDK 21-23 it pins the carrier for the whole HTTP call.
    public synchronized BigDecimal lookup(String symbol) {
        return cache.computeIfAbsent(symbol,
            s -> httpClient.quote(s));   // <-- blocks while holding the monitor
    }
}

Every cache miss blocks on the network while holding the monitor. On JDK 21–23 that virtual thread pins its carrier for the entire round trip. Run a few hundred concurrent requests and you've pinned every carrier; the rest of the workload queues behind a monitor that never unmounts. That's my 420-requests-per-second incident in five lines.

What JDK 24 changed (JEP 491)

JDK 24 shipped JEP 491, "Synchronize Virtual Threads without Pinning". It reworked monitor ownership so the monitor is associated with the virtual thread itself rather than its carrier — which means a virtual thread can now unmount while blocked inside synchronized, while waiting to enter one, or while parked in Object.wait(). The most common cause of pinning simply goes away on JDK 24+, with no code change.

Two practical consequences:

  • On JDK 24+, the only remaining pins come from native frames — JNI, FFM downcalls, and class initialization.
  • The old detection flag -Djdk.tracePinnedThreads was removed in JDK 24. Don't ship runbooks that depend on it.

If you're on JDK 21–23, though, synchronized pinning is very much alive, and upgrading is often the single cleanest fix you can make.

How to catch it

On JDK 21–23 — the legacy flag. Run with:

java -Djdk.tracePinnedThreads=full -jar app.jar

The JVM prints a stack trace every time a virtual thread pins, and the frame annotated <== monitors:1 is the culprit. That one line is the whole diagnosis. Just remember this flag no longer exists on JDK 24.

Everywhere — JFR. Since JDK 21 the JVM emits a jdk.VirtualThreadPinned Flight Recorder event when a virtual thread blocks while pinned. It's enabled by default — but with a 20 ms threshold, so short pins are invisible unless you lower it. In JDK 24 the event got better: it's emitted for every pinning occurrence and carries the reason and the carrier's identity. Since native-frame pins still fire it, this is the detection you should wire into production:

java -XX:StartFlightRecording=filename=rec.jfr,settings=profile -jar app.jar
jfr print --events jdk.VirtualThreadPinned rec.jfr

From a thread dump. Plain jstack won't show you virtual threads at all. Use the virtual-thread-aware dump:

jcmd <pid> Thread.dump_to_file -format=json dump.json

It lists the carrier threads and the virtual thread mounted on each. A carrier in the CarrierThreads group that is blocked while its mounted virtual thread sits in a synchronized frame (or a native frame) is the visual signature of a pin. Count how many carriers show it versus your pool size — that ratio tells you how close you are to full starvation.

How to fix it

  1. Swap synchronized for ReentrantLock. java.util.concurrent.locks.ReentrantLock is Loom-aware: a virtual thread that blocks on it, or while holding it, unmounts cleanly. This is the direct, version-independent fix.
  2. Upgrade to JDK 24+. JEP 491 removes the synchronized pin entirely. Native-frame pins remain.
  3. Don't hold a lock across an external call. Often the honest fix is structural: compute the value outside the critical section and only lock the map update.
  4. For native/FFM pins, isolate the path. Run unavoidable blocking native calls on a dedicated platform-thread executor, or size the carrier pool so a few concurrent pins can't starve everything.

Here's the rewrite of the example. One trap to avoid: don't just move the blocking call into ConcurrentHashMap.computeIfAbsent — as noted above, its mapping function runs under an internal bin lock, and on JDK 21–23 you'd have rebuilt the same pin one layer down.

public class PriceService {
    private final Map<String, BigDecimal> cache = new ConcurrentHashMap<>();
    private final ReentrantLock lock = new ReentrantLock();

    public BigDecimal lookup(String symbol) {
        BigDecimal cached = cache.get(symbol);
        if (cached != null) return cached;
        lock.lock();                       // Loom-aware: unmounts if it blocks
        try {
            cached = cache.get(symbol);    // re-check under the lock
            if (cached != null) return cached;
            BigDecimal quote = httpClient.quote(symbol);  // blocks; carrier is freed
            cache.put(symbol, quote);
            return quote;
        } finally {
            lock.unlock();
        }
    }
}

This no longer pins anywhere — though it still serializes cache misses behind one lock, which is fix #3's territory: the next refinement is not holding any lock across the network call at all.

Why I ended up automating the read

Doing this analysis by hand — turn on a flag, reproduce, dump, find the carriers, match frames — is fine once. It's tedious by the tenth incident, and worse, half the tooling depends on remembering to enable something before the problem happens. So I built a tool that does the read on any thread dump you give it: it finds the carriers, checks what's mounted on each, flags the pinned ones with the offending frame, and reports pinned-carriers-versus-pool-size — the number that tells you whether you're one bad path away from starvation. It's ThreadMine; the web analyzer is free and takes a dump with no signup. Full disclosure: it's my project — I got tired of reading dumps by hand, so I automated the part I kept repeating. And a fair caveat: a dump is a snapshot, so for intermittent pinning, JFR is still the better signal.

If you want the deeper reference — carriers, JEP 491, the full detection matrix — I keep it updated here: virtual thread pinning.

Pinning is the one Loom failure mode that cancels your scalability story without a single error in the logs. The rules are short: only synchronized (pre-JDK 24) and native frames pin; detect with jdk.tracePinnedThreads on 21–23 and the jdk.VirtualThreadPinned JFR event everywhere; fix with ReentrantLock, an upgrade, or by not holding locks across slow calls. Know the shape, and it stops being invisible.

Felipe Maschio is the founder of ThreadMine, a free JVM thread dump analyzer that detects deadlocks, thread leaks, pool exhaustion, CPU spikes and virtual thread pinning.

The post Your Loom App Quietly Became a Thread Pool Again: A Field Guide to Virtual Thread Pinning appeared first on foojay.

Read the whole story
jhunorss
4 days ago
reply
Share this story
Delete

Scoped Values: A Better Alternative to ThreadLocal for Virtual Threads

1 Share
Read the whole story
jhunorss
5 days ago
reply
Share this story
Delete

Data Broker Radaris Loses Domains in Privacy Fight

1 Share

The consumer data broker Radaris.com has long had a reputation for ignoring requests to remove personal information from its vast empire of people-search services online. That reputation caught up with the company recently in a lawsuit alleging Radaris violated a New Jersey privacy law that provides for hefty fines against data brokers that publish personal information on state law enforcement officials. In the face of repeated stonewalling and prevarication by attorneys for Radaris, the judge in the case ordered that radaris.com and more than a dozen other data broker domains be transferred to the plaintiffs.

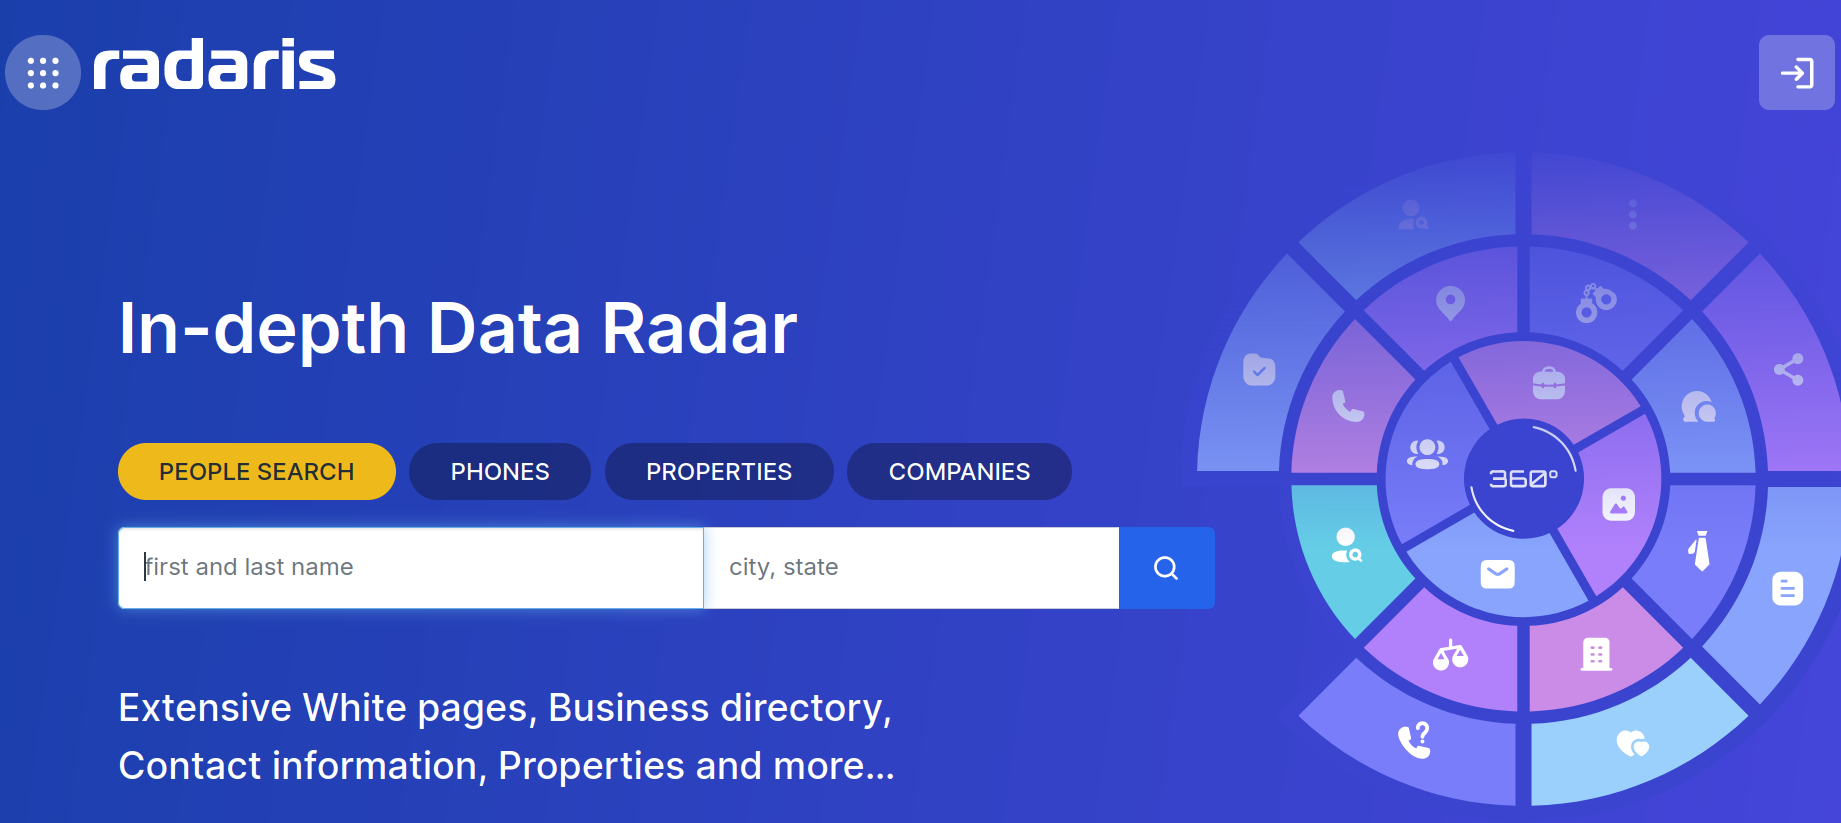
The radaris.com website, prior to the domain transfer to Atlas.

In February 2024, Radaris was sued by Atlas Data Privacy Corp, a company that has been pursuing data brokers alleged to be violating a New Jersey statute called Daniel’s Law. The statute allows state law enforcement officials, government personnel, judges and their families to have their information completely removed from commercial data brokers and people-search services, and provides for fines of $1,000 per violation against companies that ignore removal requests.

Less than a month after Atlas sued Radaris, KrebsOnSecurity published a deep dive into the Radaris co-founders — Igor and Dmitry Lubarsky (also spelled Lybarsky) — Russian-born brothers living in Massachusetts who operate a dizzying array of people-search companies as well as a number of Russian language dating services and affiliate programs.

Attorneys for the Lubarsky brothers threatened to sue for defamation if the story wasn’t removed and an apology issued. Their attorney asserted that our reporting was wildly inaccurate, and that the true owners of the company were Ukrainians living in Ukraine.

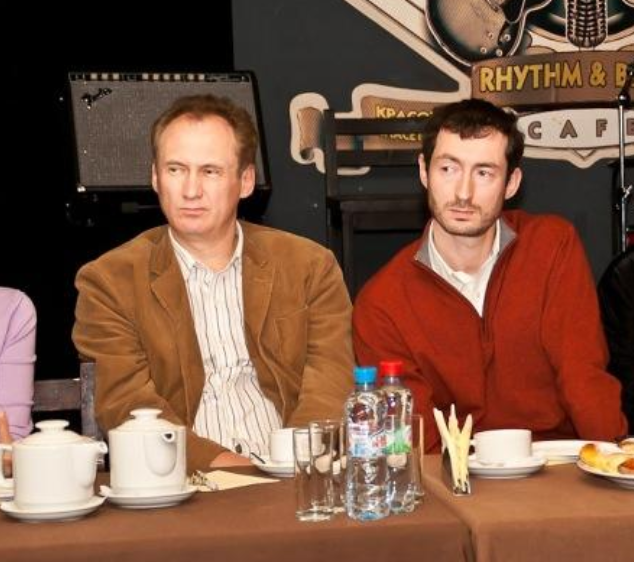
The Lubarsky brothers Dmitry or “Dan” (left) and Gary/Igor.

KrebsOnSecurity doubled down and showed how the Lubarsky brothers built and operated Radaris and other data broker companies using a fictitious CEO’s name. Our follow-up story noted that Radaris’s attorney — a lawyer with the Boston Law Group named Val Gurvits — admitted his clients had invented the CEO pseudonym “Gary Norden,” and that Radaris also had issued multiple press releases over the years that quoted the fake CEO while seeking money from potential investors.

Attorneys for Radaris waited until the last minute to appear in court and contest what was all but certain to be a default judgment in favor of the plaintiffs, and then told the court that Atlas had failed to serve the real owners and operators of Radaris and several of its sister data broker companies.

Atlas re-filed the lawsuit in June 2025, this time dramatically expanding the number of Radaris family data brokers accused of violating Daniel’s Law. Matt Adkisson, president and CEO of Atlas, said Radaris turned to a tried-and-true playbook: Delaying in court until the last possible minute, and playing shell games with Radaris’s true country of origin and the individuals listed as owners and operators of these sites.

“We refer to this period as their island-hopping phase. Privacy policies changed constantly, and new entities kept appearing from places like the Marshall Islands, the British Virgin Islands, and Seychelles,” Adkisson told KrebsOnSecurity. “Behind the scenes, it felt like a shell game. Defense lawyers told the court that certain entities merely operated the domains and were the proper parties to sue. But by the time a judgment neared, those entities would be discarded and new entities would appear. Meanwhile, the lawyers claimed the other entities that actually owned the domains should not be held responsible.”

Adkisson said when the defendants updated their terms of service to state that Radaris was suddenly managed by a company in the Marshall Islands, Atlas hired an investigator in that country and soon learned the brand new entity that Radaris claimed was managing the company didn’t even exist yet.

Mr. Gurvits stepped forward as Radaris’s attorney in a class action lawsuit the company temporarily lost in 2017 because it never contested the claim in court. When the plaintiffs told the judge they couldn’t collect on the $7.5 million default judgment, the court ordered the domain registry Verisign to transfer the radaris.com domain name to the plaintiffs.

Mr. Gurvits appealed that verdict, arguing the lawsuit hadn’t named the actual owners of the Radaris domain name — a Cyprus company called Bitseller Expert Limited — and thus taking the domain away would be a violation of their due process rights.

The judge in the 2017 case ruled in Radaris’ favor — halting the domain transfer — and told the plaintiffs they could refile their complaint. Soon after, the operator of Radaris changed from Bitseller to Andtop Company, an entity formed (PDF) in the Marshall Islands in Oct. 2020. The plaintiffs never re-filed their lawsuit.

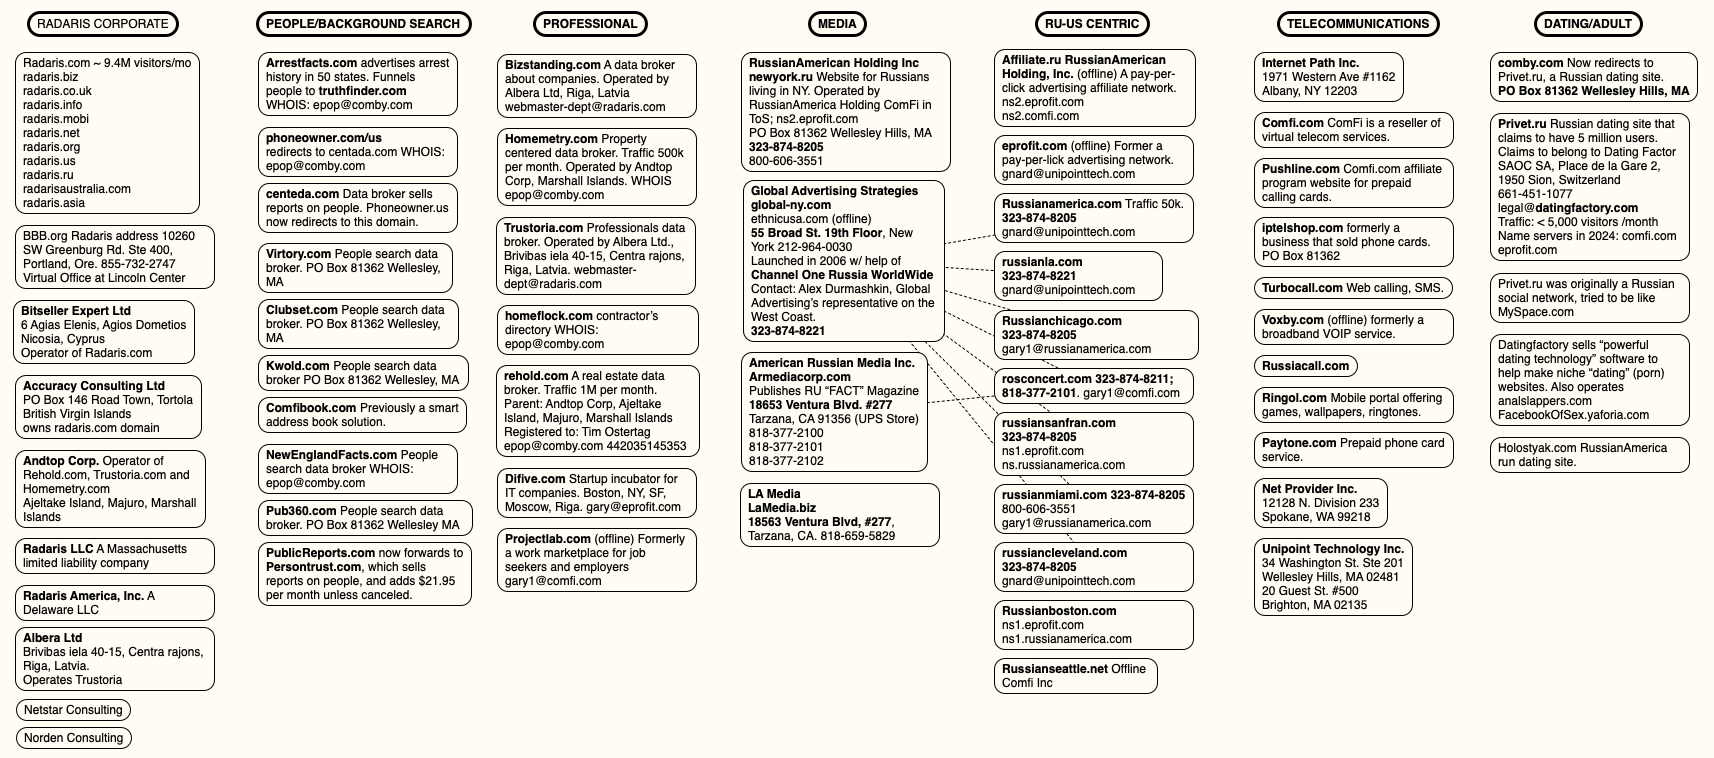
A mind map of various entities tied to Radaris and the company’s co-founders. Click to enlarge.

“That seemed to be their modus operandi,” said Raj Parikh, a partner at PEM Law in New Jersey who handles most of the Daniel’s Law litigation for Atlas. “In the past, they won by attrition. Plaintiffs’ attorneys tired of the procedural games and just gave up. That strategy worked for a decade, and it probably would have worked in this case too, since any financial recovery from foreign actors will be difficult. But we were acutely aware of the threat this website posed to law enforcement officers and other public officials in New Jersey, and decided early on to commit whatever time and resources were necessary to remove that threat.”

On August 26, the judge in the New Jersey case found the defendants were given multiple chances to appear and defend the claims against them but had failed to do so. Mr. Gurvits declined to comment on the case, saying it had been assigned to another attorney, a Mr. Victor Worms. In response to questions, Mr. Worms asserted the New Jersey court transferred Radaris.com to Atlas as part of a default judgment against Radaris.com, which is not a legal entity.

“We have made a motion to vacate that default judgment on the grounds that it is void since a non-entity has no legal capacity to sue or be sued,” Worms replied. “We also intend to pursue all appropriate appeals because we believe the transfer of Radaris.com amounts to a forfeiture in violation of various constitutional principles.”

While radaris.com still comes up prominently in results when searching online for U.S. residents by name, the domain no longer sells detailed personal dossiers on millions of Americans. Its homepage now displays a notice from Atlas, as well as links to our previous reporting on Radaris.

EMAIL CONFIRMATIONS

Atlas told KrebsOnSecurity that it has obtained more than 10,000 emails and documents in the course of litigation, and that those messages confirm our previous reporting on the owners and operators of Radaris and its myriad companies.

Atlas said the emails clearly establish that the nominal legal vehicles — Radaris America, Inc.; Bitseller Expert Limited; Digital Orbit Corp; Core Solutions Group Inc; Lucky Solutions Inc; Virtura Corp; Veripages Inc.; Nuform Solutions Inc.; Growth Data Advisors Inc.; Property Experts, Inc — are all administered by the same three or four people from the same mailboxes, share one bank or payment card set, and are all managed from one virtual office address.

“The corpus establishes, with documentary evidence generated independently by banks, payment processors, hosting providers, registrars, software-as-a-service vendors and the operators’ own systems, that radaris.com and at least twenty-five other people-search websites are one operation run by a small Boston-area group whose administrative, financial and technical functions sit on the difive.com mail domain and its successors (centerex.com, scienteco.com, eprofit.com, realmo.com, pub360.com),” reads a summary shared by Atlas.

Atlas said the emails show Radaris.com earns approximately $42,000 a month, while Veripages.com earns around $45,000 monthly via its partnership with the Lifetime Value Company, a marketing and advertising firm whose brands include PeopleLooker, PeopleSmart, NumberGuru, and Bumper, a car history site.

According to Atlas, the emails also showed the Radaris family of websites earns as much as $25,000 each month from their partnership with Onerep, a company that claims to help people remove their information from people-search sites. In March 2024, KrebsOnSecurity revealed how the Belarusian founder of Onerep had launched and operated dozens of people-search sites over the years and was continuing to operate one of them (Nuwber), effectively spreading the disease and selling the cure.

The domain radaris.com now redirects to this notice from Atlas about the court-ordered domain transfer.

The domain radaris.com now redirects to this notice from Atlas about the court-ordered domain transfer.

All told, the New Jersey court has so far transferred 14 domain names from the Radaris family of companies to Atlas. Radaris.com now redirects to a notice of the court-ordered domain transfer.

THE ROAD AHEAD

The Radaris family of companies is still potentially facing fines of $1,000 per alleged violation of Daniel’s Law. For the time being, however, Daniel’s Law is facing a constitutional challenge from virtually all of the 150 other consumer data broker firms being sued by Atlas.

The data broker industry responded by having at least 70 of the Atlas lawsuits moved to federal court, challenging the New Jersey statute as overly broad and a violation of the First Amendment. The U.S. Court of Appeals for the Third Circuit has not yet issued a decision on the constitutional challenge, but either way the case is widely expected to be appealed all the way to the U.S. Supreme Court.

Meanwhile, at least 14 other states have now passed laws modeled after the New Jersey statute, with more states considering similar measures. However, West Virginia’s Daniel’s Law was ruled facially unconstitutional under the First Amendment by a federal district court in August 2025.

Justin Sherman is a privacy expert and author of the forthcoming book “The Middlemen,” which examines how the data broker industry powers modern surveillance. Sherman said federal lawmakers have long faced intense lobbying by the technology industry against more restrictive U.S. data privacy laws, but that many powerful industries are now working against passing comprehensive data privacy legislation.

“These days at the federal level, add in the intense amount of lobbying against these laws from social media companies, big tech, cryptocurrency firms, and now AI proponents in the mix who claim that limiting their data scraping is somehow going to collapse the whole U.S. economy under Chinese rule,” he said.

Sherman said people-search companies will continue to thrive unless and until Congress enacts meaningful consumer privacy and data protection laws that are relevant to life in the 21st century. That’s because virtually all state privacy laws exempt records that might be considered “public” or “government” documents, including voting registries, property filings, marriage certificates, motor vehicle records, criminal records, court documents, death records, professional licenses, bankruptcy filings, and more.

At least 25 states have passed or implemented laws requiring age verification for residents seeking to access adult content online, but there is no federal law that limits how the companies that are scanning everyone’s drivers license can use, share or keep the data provided. Had such restrictions been enshrined in law, we may have avoided the recent breach at IDScan.net, which exposed the drivers license information on more than 153 million Americans when the records were briefly turned into a point-and-click identity theft service on the dark web.

“The average person can look at Daniel’s Law and have a perfectly normal reaction, which is that everyone should be covered, not just police and judges,” Sherman said. “But we don’t need more wake-up calls. We’ve had eight million wake-up calls already on the need for better privacy laws. The lack of comprehensive federal privacy law is not for a lack of knowledge, and anyone claiming otherwise is either not reading the news or kidding themselves.”

Read the whole story
jhunorss
5 days ago
reply
Share this story
Delete

Schlimmer als Stoppschilder fürs Internet: Der EU Kids Act

1 Share
Die EU-Kommission hat einen Entwurf zum „EU Kids Act“ vorgestellt. Er bedeutet nichts Gutes für die Zukunft des freien und fairen Internet: Anstatt Kinder wirklich zu schützen, bedeutet er das Ende jeglicher digitaler Teilhabe für Jugendliche unter 18, einen tiefen Grundrechtseingriff für alle und eine Gefahr für Alternativen zu Big Tech.
Read the whole story
jhunorss
5 days ago
reply
Share this story
Delete

Flock cameras are riddled with security vulnerabilities and hard-coded credentials

1 Comment and 2 Shares
Flock cameras are riddled with security vulnerabilities and hard-coded credentials

This morning, DDoSecrets published an exciting new dataset: Filesystem images of the partitions from an in-use Flock ALPR camera. 404 Media and Wired published a joint investigation into it. I downloaded the dataset and am now thoroughly nerd-sniped.

Hackers from a collective called stegan0gram collected the data. “Why just destroy [Flock cameras] when we can reverse engineer them and find the secrets of those spying on us?” one of the hackers told 404 Media and Wired in an interview. “We liberated hardware in the field, disarmed them, and proceeded with reverse engineering of the cameras and associated solar equipment.”

Below are a few of the secrets that I've found so far.

I'm crunching data and writing these newsletters in my free time. If you want to support my work, consider becoming a paid supporter.

Become a paid supporter

This camera is running an obsolete, end-of-life version of Android

Flock cameras run on a modified version of Android. The specific build that this Flock camera was running at the point in time the firmware was extracted was from June 5, 2025.

Despite being a relatively recent build, the Flock camera was running Android 8.1. This version of Android was released in 2017, and officially stopped getting support from Google in 2021 (see the Android end-of-life page for more info). And despite Google publishing security fixes for Android 8.1 until 2021, the Android patch level is 2018-06-05. This camera is missing Android security updates for the last eight years.

Android runs on the Linux kernel. This Flock camera was running Linux 3.18.71, released in 2017. The 3.18 series was maintained until May 2019, ending at 3.18.140 — this camera is 69 releases short of even that. This kernel is over nine years out-of-date.

Here are a few publicly-known vulnerabilities that this camera is probably vulnerable to, and that affect components that this camera ships with. I don't actually have this Flock camera to test these on and confirm that the hacks work, but what I do know is that this Flock camera's patch level predates all of these vulns, despite patches being available for many years.

  • CVE-2021-1905 Qualcomm Adreno GPU – use-after-free. Any code running on the Flock camera, including in unprivileged apps, can corrupt kernel memory through the GPU driver and take full control of the device. Patched in May 2021.
  • CVE-2018-9568 ("WrongZone") – kernel socket type confusion. A program running on the camera can confuse the kernel's socket handling over IPv6 and escalate itself to root. Patched in December 2018. (Here's public exploit code for this one.)

In a statement to 404 Media and Wired, a Flock spokesperson said:

Flock takes security seriously and maintains a public Vulnerability Disclosure Policy for security researchers to report potential vulnerabilities directly to us. We received no report through that process, and based on the limited information provided, we do not have enough detail to assess the claims being made. If the individuals identified legitimate vulnerabilities, we encourage them to submit their technical findings through our vulnerability reporting process so our security team can review them and take any appropriate action.

lol.

Where I found this in the data

If you want to follow along, DDoSecrets published this dataset here.

The Android version and patch level are listed in multiple places, but the easiest place to find it is in the system partition. If you download partitions/24_system.img (1.5 GB) and extract it, you'll find a file, build.prop, which includes these lines:

ro.build.version.sdk=27
ro.build.version.release=8.1.0
ro.build.version.security_patch=2018-06-05
ro.build.date=Thu Jun  5 20:05:57 UTC 2025

The Linux version can be found in the boot partition. If you download partitions/21_boot.img (32 MB) and extract it, you'll find the kernel image in a file called kernel. You can find the Linux version with:

❯ tail -c +16496 kernel | zcat 2>/dev/null | grep -am1 'Linux version'
Linux version 3.18.71-perf-gaf770dc (android@e593ce924ef6) (gcc version 4.8 (GCC) ) #1 SMP PREEMPT Thu Jun 5 20:15:45 UTC 2025

Credentials into Flock's live production infrastructure

Before I go into detail here, I want to emphasize something real quick:

It's illegal to connect to Flock's servers using leaked credentials without their permission.

The Android firmware for this Flock camera includes 20 separate Flock apps, 19 of which all share a library called com.flocksafety.android.common.lib. If you decompile the library, there's an interesting method in the CameraSettings class:

public final String getHpnotiqApiKey() {
    return "HaJ3FgupAm8RrDJW3MHgT9X7Ft27eVaD";
}

This is an API key, hard-coded straight into the app. Flock runs a backend service at hpnotiq.flocksafety.com. When the camera needs new credentials, it makes an API request to hpnotiq that looks like this:

POST https://hpnotiq.flocksafety.com/api/v3/devices/credentials
x-api-key: HaJ3FgupAm8RrDJW3MHgT9X7Ft27eVaD

macAddress=F46ADD5746FB

Note that this specific Flock camera's MAC address is F4:6A:DD:57:46:FB.

Presumably, you can use this hard-coded API key to obtain credentials for any Flock camera, based on its MAC address.

The API appears to respond with an Auth0 client ID and secret. Auth0 is an identity management company owned by Okta. The camera then stores those credentials in plaintext.

Btw, those credentials, which might actually still be live and active (I'm honestly not sure because I didn't try them), are:

{
    "clientId":"CPkOAuOKFwNhPavKO01Htxbn6yIwASro",
    "clientSecret":"ZRExGjbVjBB1wx04RmsMeWKbpMO5zQxLKNZg25D-1LUKbfQbmByajx-8lyB6LwSV"
}

These credentials can then be used to mint bearer tokens by sending them to https://device-login.flocksafety.com/oauth/token, and getting back a short-lived FlockAuth0Token which can be used to interact with Flock's backend servers, authenticated as this camera.

Where I found this in the data

The API key is in the system partition. Download partitions/24_system.img (1.5 GB), extract it, and you'll find 19 Flock apps under app/: flock-sambuca, flock-collins, flock-phone-home, etc., each containing an APK. Decompile any one of them and look for CameraSettings in com.flocksafety.android.common.lib. The shared library is bundled into all 19 apps, so the key is in every one of them.

flock-sambuca is the app that uses it for provisioning credentials. Its Auth0ServiceManager class builds the credentials request, and the URLs for both hpnotiq.flocksafety.com and device-login.flocksafety.com are in that APK's string resources (resources/res/values/strings.xml).

The Auth0 client ID and secret are on a different partition. Download partitions/27_persist.img (32 MB) and extract it. The file is at flock/auth0/auth0_cred. This is the camera's /persist partition, which is not encrypted and is designed to survive a factory reset.

The MAC address and the 2,264 calls to hpnotiq come from the camera's logs, in partitions/53_media.img (18 GB). Those sit inside an encrypted container, though the key to it is stored on the same partition in a file called expand_1fcdafef903c40cab3aff81bec914d01.key, lol. Once it's unlocked, the logs are gzipped tarballs under media/0/media/crashpack/.

This specific camera was in a suburb of Milwaukee

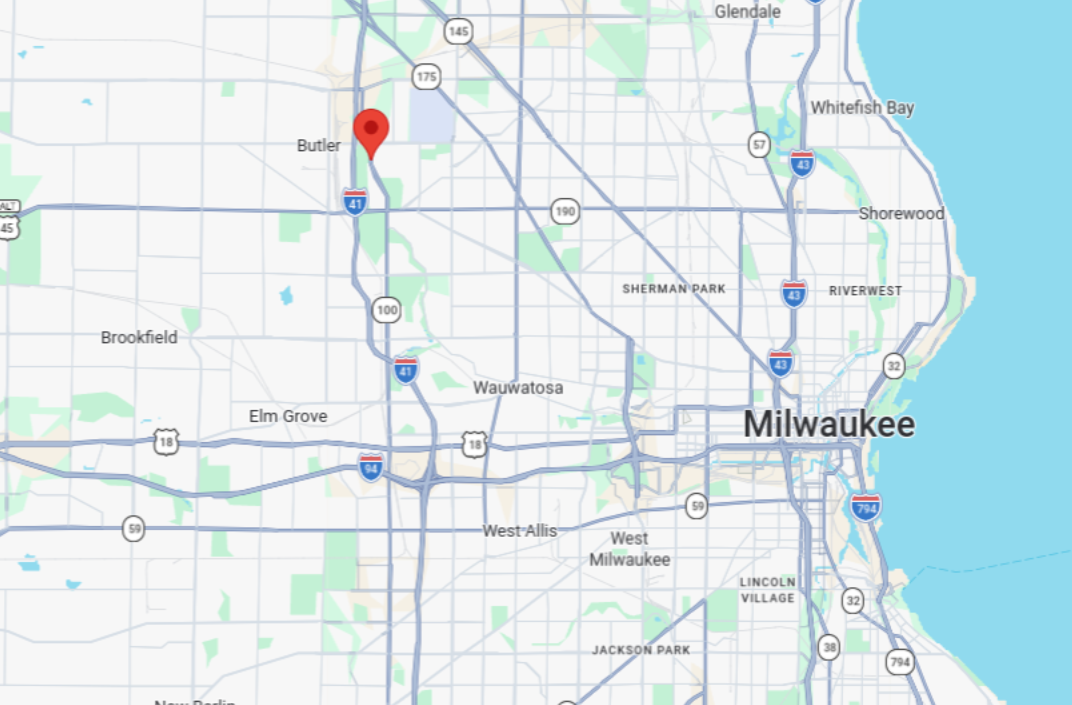
The Flock camera's logs include camera location GPS coordinates 155 times, all within about 100 meters of each other, which I think is ordinary GPS jitter for a receiver that never moves. The coordinates that appear most often are 43.10151313, -88.05270186. If you search for that in Google Maps, you'll end up in a suburb just northwest of Milwaukee.

Flock cameras are riddled with security vulnerabilities and hard-coded credentials
The coordinates 43.10151313, -88.05270186, from Google Maps

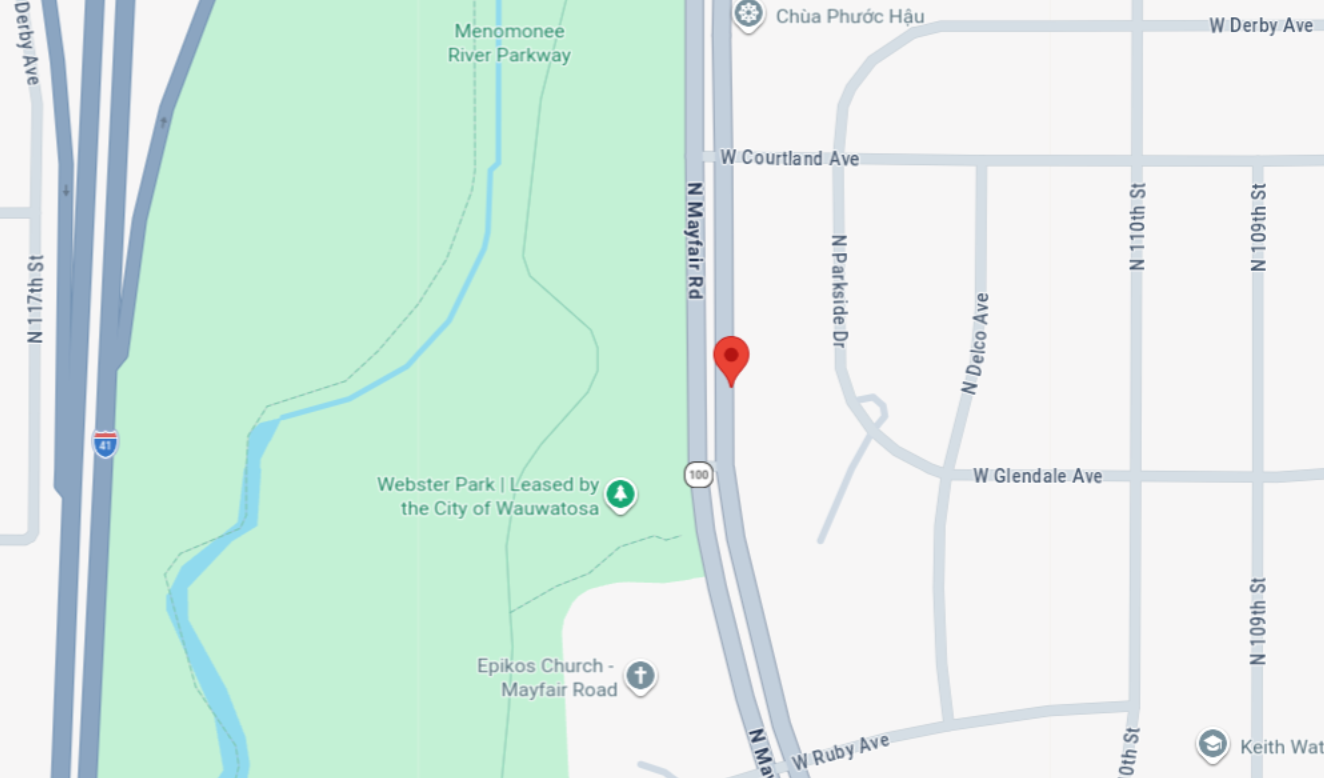
I've never been to the Milwaukee area, but it looks like this Flock camera is in a city called Wauwatosa, on N Mayfair Rd, just off of Webster Park.

Flock cameras are riddled with security vulnerabilities and hard-coded credentials
Zoomed into the camera's location

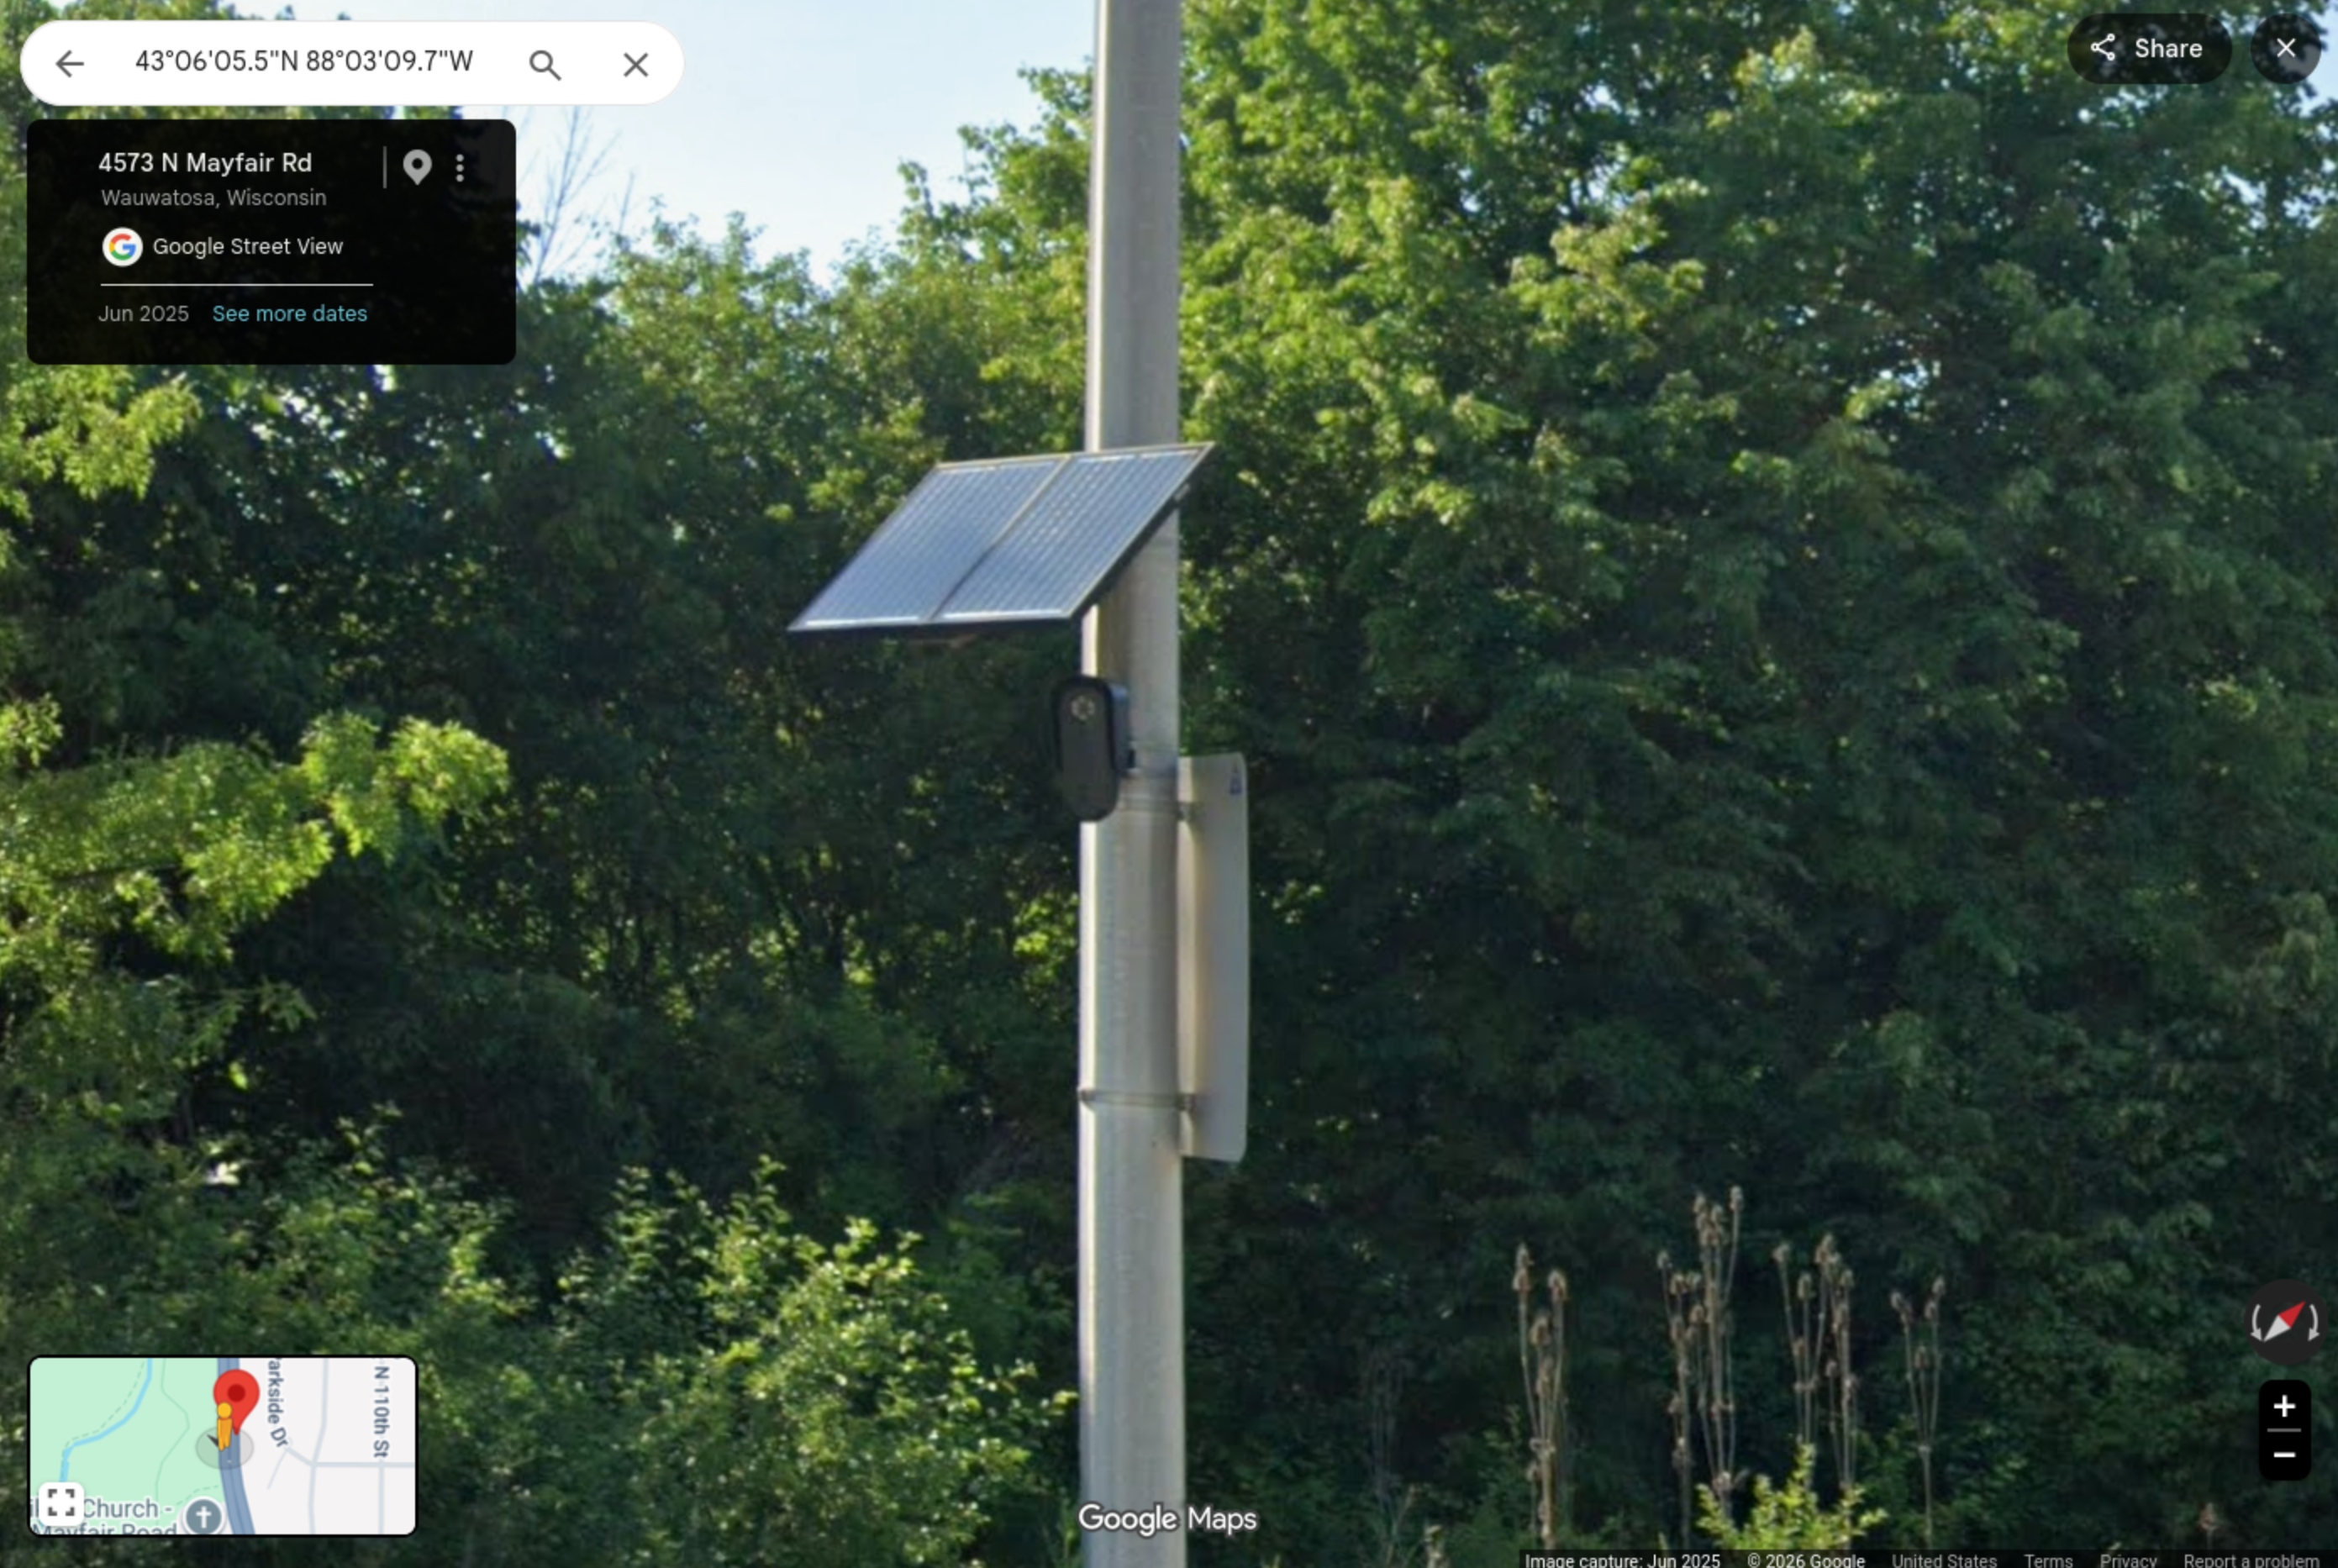
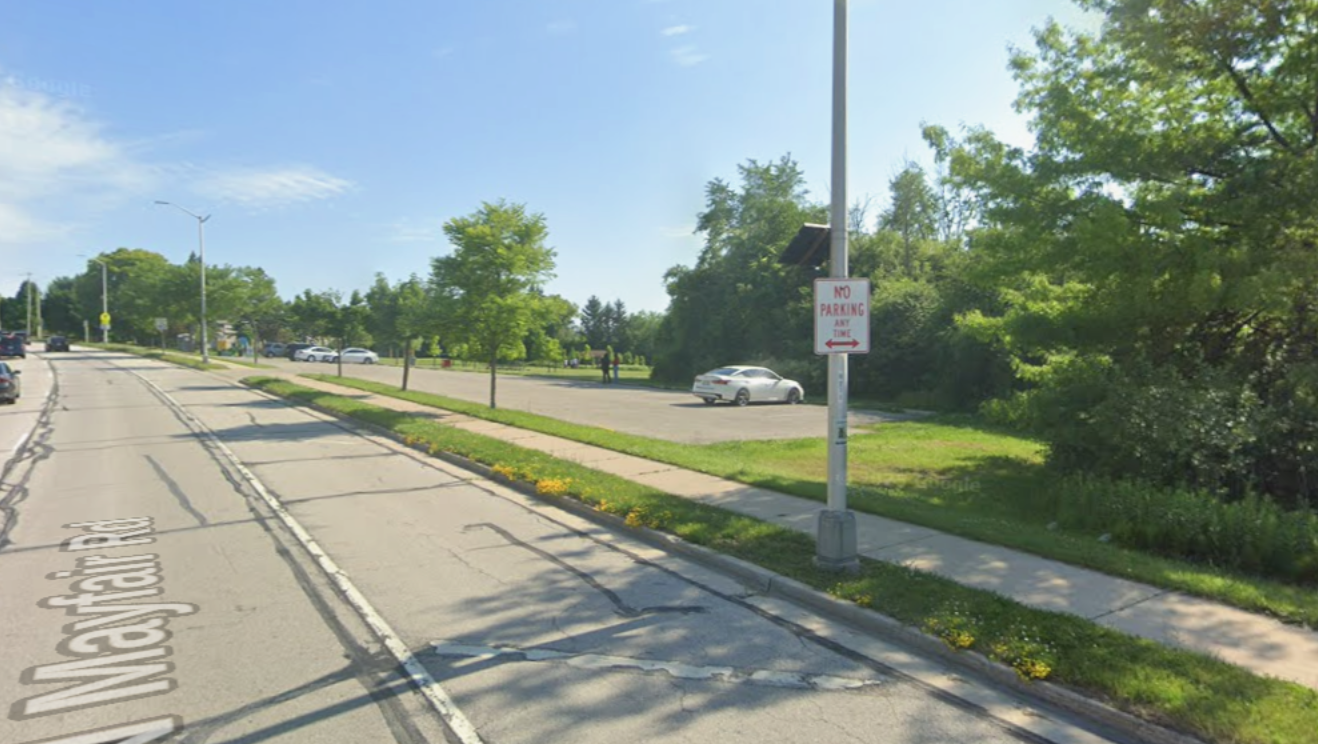
Using Google Street View, I walked around N Mayfair Rd looking for a Flock camera. It looks like the GPS is slightly off, and it's actually on the west side of the street, near a parking lot for the park.

Flock cameras are riddled with security vulnerabilities and hard-coded credentials
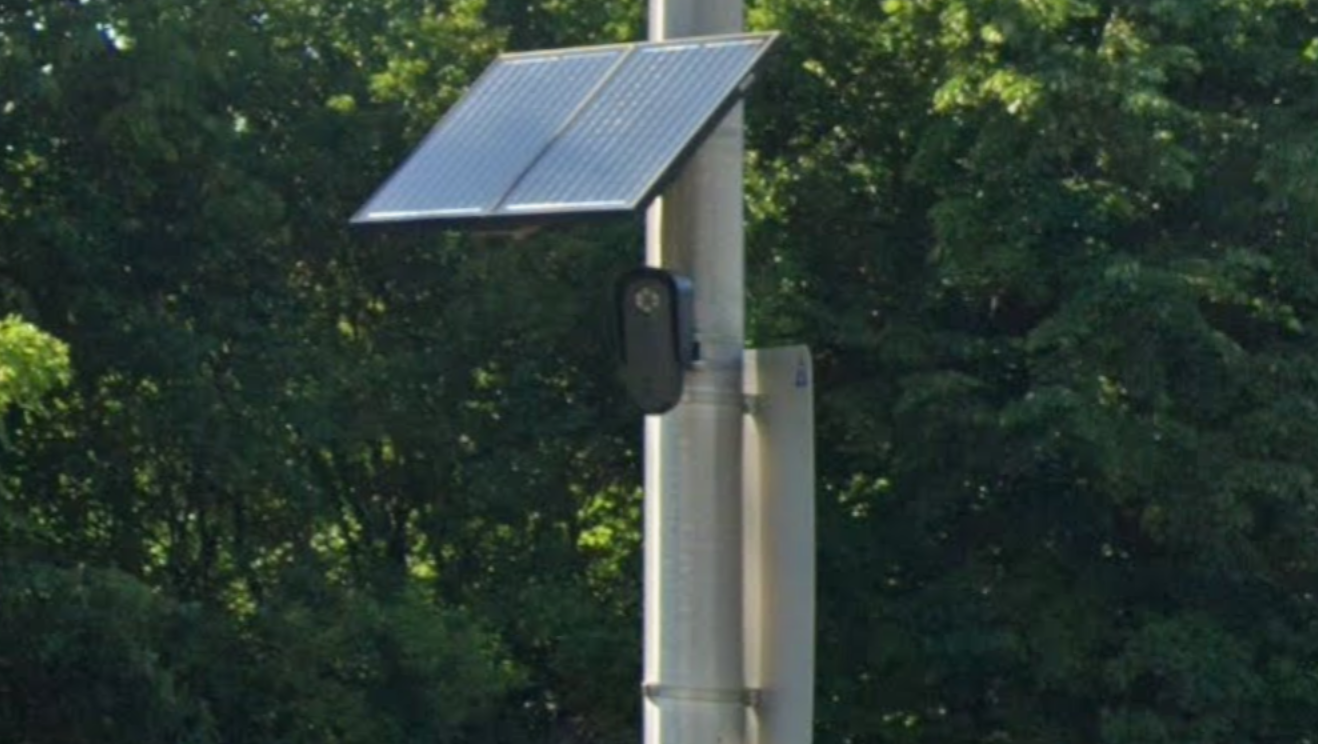
See the solar panel on that light post with the No Parking sign? That's the Flock camera.

There you are, Flock camera serial number 23091220026 with MAC address F4:6A:DD:57:46:FB!

Flock cameras are riddled with security vulnerabilities and hard-coded credentials
The Flock camera in question, captured by Google's surveillance infrastructure

Who could have realized that this little camera, spending all its time spying on the innocent people driving by, would some day find its way into the hands of hackers from the stegan0gram collective?

Where I found this in the data

Download partitions/53_media.img (18 GB), extract it, mount the (barely) encrypted filesystem, and then look at the logs in media/0/media/crashpack/. Extract one of the log files – any of them, it doesn't matter. Inside there, there are many logs with filenames like ciroc.2026-*.log. Grep those for Location and you'll see the GPS coordinates:

❯ cat ciroc.2026-01-27.3.log | grep Location
01-28 08:22:31.304 INFO  [Binder:1584_1] QCamera2: Location: 43.10151313, -88.05270186
01-28 08:32:32.240 INFO  [Binder:1584_3] QCamera2: Location: 43.10151313, -88.05270186
--snip--

With luck, this reporting will encourage city councils everywhere to cancel their contracts with Flock and other ALPR vendors, and to stop giving the police more surveillance tools at the expense of everyone's privacy.

Read the whole story
jhunorss
7 days ago
reply
Share this story
Delete
1 public comment
jgbishop
7 days ago
reply
Ha! This is both incredible and yet not surprising.
Raleigh, NC
Next Page of Stories